Fasta and Fastq sequences
Fasta format
Right, now that you have learned the basics of Linux, let’s also look at some sequence formats to represent sequenced reads or assembled genomes, transcriptomes and translated protein data.
The first format we are going to talk about is the fasta format.
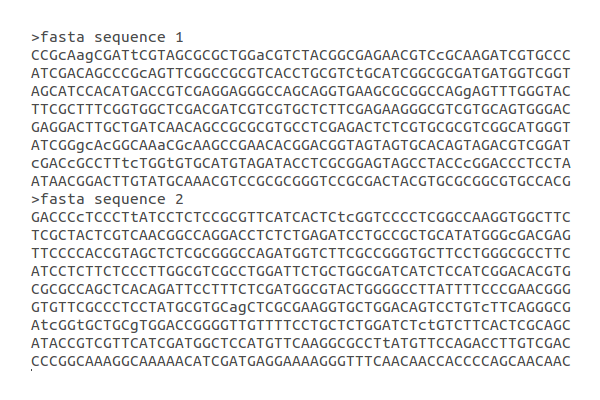
In the image above you see two DNA sequences in a multifasta file. A fasta sequence is basically a text file where first you see the symbol ‘>’ followed by the ID of the sequence. Then, on the next line you see the nucleotide sequence. If the file is a multifasta file - like in this case - the next line will have the symbol ‘>’ again followed by the ID of the second nucleotide sequence, and so on. Fasta sequences can also represent protein sequences.
Fastq format
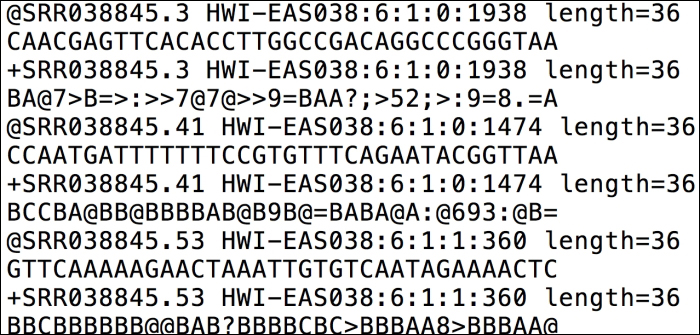
The first line of a fastq sequence starts with “@” followed by the ID. On the second line you have your nucleotide sequence. On the third line you have a “+” followed by a fourth line which represents base pair quality.
Attention 
Fasta and fastq IDs can be as long as you like. But be careful with length: many algorithms crash with long-read-IDs. Secondly, differently than the first image above that illustrates a fasta sequence, you should avoid spaces in IDs before you have a unique pattern in the ID. For example, you should have:
> Sequence1 H.sapiens
ACGATGCTAGATGAT
>Sequence2 H.sapiens
CCAGTAGATAGATAGAAAAA
Unique patterns before any other information, such as “H.sapiens”, that you want to have in your ID. We will see examples of why.
Command line utilities
Because our files have defined patterns, we can use command line utilities that deal with regular expressions. Let’s do it.
You have a ‘Day1.fasta’ file in our data folder. Let’s copy this file to our Linux training folder.
cp <path_to_data_folder>/Day1.fasta .
Right, now you can use less or more to have a look at the file:
less Day1.fasta
Right, doing this I can see this is a fasta file. But let’s say I want to know how many reads I have in this file. ‘Lessing’ it is not very useful for such. But we can use [grep]